Model · speech-to-text
Fritter: Parakeet TDT 0.6B v2 fine-tune for technical English dictation
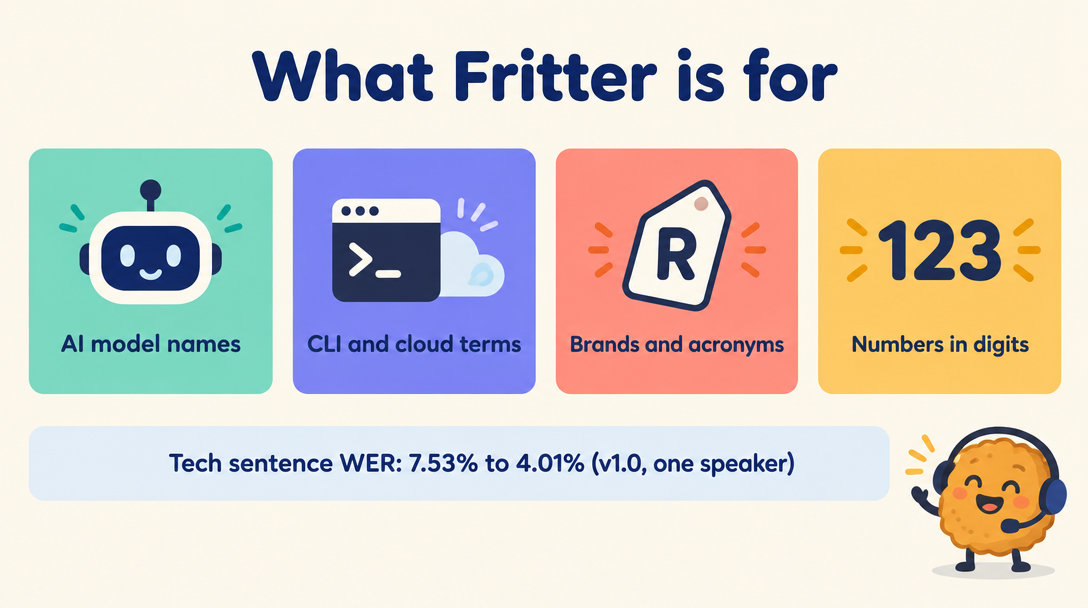
An English dictation model tuned for technical vocabulary: AI model names, CLI and cloud terms, brands, acronyms and numbers in digits.
About the model
Fritter is a full fine-tune of NVIDIA Parakeet TDT 0.6B v2 for English dictation. It targets the words stock speech models get wrong in technical work: AI model and product names, CLI and cloud terms, brand names and acronyms. Numbers and currency come out in digits, and output keeps Parakeet's casing and punctuation.
It is public and ungated, in every format a local app needs: .nemo, GGUF for transcribe.cpp, ONNX, and a sherpa-onnx int8 build. App developers are welcome to offer it to their users or list it in a model catalogue, for non-commercial use with attribution.
It is trained on one speaker, me: an English speaker with an Irish accent living in Israel. The test results below come from held-out recordings of the same voice, so expect smaller gains on other voices. Those gains have not been measured.
v1.2 (2026-11-05) is the current version. The numbers below are v1.0's, the last version benchmarked. A streaming version, Fritter Nemotron v1.0 (2026-11-05), runs on Nemotron Speech Streaming EN 0.6B and is not benchmarked yet: its validation WER of 5.83% only picks the checkpoint. Both are trained on one speaker, so other voices may gain less.
Which file should I download?
If unsure, take Q8_0. On desktop CPUs it was also faster than Q4_K_M (about 3× realtime against 1.4× on 8 cores), and both gave the same transcripts as the full model on the test clips.
GGUF Q8_0 730 MB
The recommended file for phones and laptops. Imports into Offline Voice Input; made with transcribe.cpp v0.1.3.
Run with transcribe.cpp Download GGUF Q8_0 →GGUF Q4_K_M 475 MB
Smaller quant for devices short on memory.
Run with transcribe.cpp Download GGUF Q4_K_M →sherpa-onnx int8 661 MB
Offline transducer for apps built on sherpa-onnx, on Android, Linux and Windows.
Run with sherpa-onnx Download sherpa-onnx int8 →sherpa-onnx int8, direct 661 MB
The same build outside Hugging Face, always the latest version. The manifest lists each file with its size and sha256.
Run with sherpa-onnx Download sherpa-onnx int8, direct →Streaming sherpa-onnx int8, direct 662 MB
Fritter Nemotron v1.0 for live dictation, 560 ms chunks, always the latest version. Carries the NVIDIA notice on its Hugging Face repo.
Run with sherpa-onnx Download Streaming sherpa-onnx int8, direct →Streaming .nemo checkpoint 2.47 GB
Fritter Nemotron v1.0 at full precision. A GGUF F16 for transcribe.cpp (1.24 GB) sits beside it.
Run with NVIDIA NeMo Download Streaming .nemo checkpoint →ONNX int8 661 MB
The istupakov/onnx-asr layout, for Voxtype and onnx-asr. An fp32 build (2.5 GB) sits beside it.
Run with onnx-asr Download ONNX int8 →.nemo checkpoint 2.47 GB
Python, GPU inference or further fine-tuning, at full precision.
Run with NVIDIA NeMo Download .nemo checkpoint →On Android
- Install Offline Voice Input (source), download the Q8_0 GGUF on the phone, import it in the app and select it.
- Use it as the system voice input, or through a keyboard whose mic key opens it: SwiftKey, HeliBoard or FlorisBoard. Gboard's mic button cannot hand speech to it.
- Set the app's battery optimisation to Unrestricted so Android does not kill it between dictations.
On Linux
- Handy loads the same GGUF. Copy it into
~/.local/share/com.pais.handy/models/under its own file name.
Results
Fritter v1.0, run r11-general, evaluated 27 October 2026. Lower WER is better; a higher share of terms correct is better.
Newer releases not yet scored: v1.1 and v1.2 were published without a benchmark. These results are v1.0's.
| Test set | Stock v2 | Fine-tune Fritter v1.0 |
|---|---|---|
| Tech sentences, 213 clips (WER) | 7.53% | 4.01% |
| Target-term recall, unseen terms (447 occurrences, 262 terms) | 65.1% | 79.6% |
| Numbers recall, 62 tokens | 33.9% | 50.0% |
| Speaker's own English, 364 clips (WER) | 7.23% | 4.85% |
| LibriSpeech test-clean, 200 clips (WER) | 1.23% | 1.47% |
| Long form, about 3 minutes per file, 23 files (WER) | 11.05% | 12.16% |
- Held-out recordings of the same speaker (dataset revision 520e7506), never trained on. WER is normalised: lowercase, punctuation removed.
- The test split is term-disjoint, so every scored term is one Fritter never heard in training. Biggest category gains: linux 5.2% to 0.7%, ai_interactions 7.3% to 2.6%.
- General English is slightly worse than stock: 0.24 points on LibriSpeech and 1.11 points on long files.
Training
- Fritter Nemotron v1.0 (run r31-nemotron-general, 2026-11-05): full fine-tune of Nemotron Speech Streaming EN 0.6B from stock on 858.8 minutes of my own recordings plus 95.6 minutes of LibriSpeech replay, 20 epochs, one L40S on Modal.
- v1.2 (run r30-general, 2026-11-05): continued from v1.1 on 210.0 minutes of new recordings plus a replay sample, lr 1e-5, 3 epochs, one L40S on Modal.
- v1.1 (run r25-general, 2026-11-03): full fine-tune from stock on 694.8 minutes of my own recordings plus 77.3 minutes of LibriSpeech replay.
- v1.0 (run r11-general, 2026-10-27): full fine-tune from stock on 319.9 minutes of my own recordings plus 35.6 minutes of replay.
Training data
Checkpoints and roadmap
Where the model is now and the checkpoints still to come. Planned stages are the current plan, not promises.
- v1.0 (r11-general) Done 27 October 2026
First release under the Fritter name, with GGUF, ONNX and sherpa-onnx builds and a browser demo.
- v1.1 (r25-general) Done 3 November 2026
Fresh full fine-tune on about 2.2 times the audio.
- v1.2 (r30-general) Done 5 November 2026
First incremental update, every build refreshed.
- Fritter Nemotron v1.0 (r31-nemotron-general) Done 5 November 2026
First streaming release, on Nemotron Speech Streaming EN 0.6B, for live dictation. Same licence. Not benchmarked yet.
Limitations
- Trained on one voice. Accuracy on other speakers has not been measured.
- v1.1, v1.2 and Fritter Nemotron v1.0 are not benchmarked.
- Still weak on unseen proper names and alphanumeric codes.
- Slightly worse than stock on general English and long files (see the results).
- Non-commercial licence. The streaming build is also licensed by NVIDIA Corporation under the NVIDIA Open Model License (see NOTICE on its Hugging Face repo). Not made or endorsed by NVIDIA.
Related
- Fritter on Carrot Cake AIBoth builds with every direct download link
- Blog postBackground on the model
- Release postThe streaming version and direct downloads