Daniel Rosehill · AI

AI that works for the people the defaults leave out

Most of my AI work comes back to one question: how do we make this technology work for people who don't fit the default? English speakers in Israel who mix in Hebrew, people who'd rather speak than type, and anyone who wants agents that do real work. I build it in the open: models, datasets, evals and the tooling around them.

Explore

Flagship project

Hebrish: speech-to-text that keeps the Hebrew

Stock speech models turn the Hebrew words in an English sentence into nonsense. Hebrish models keep them. Compare stock and fine-tuned output on real recordings below, then see the model lineup or hebrish.app ↗.

Same recording. Two models. Real output on clips neither model was trained on.
Stock Parakeet guesses English

Yes, you can pay with the Cartisa Shrai, but if you pay him as Uman, there's a small discount.

Hebrish Jachnun v1.0 writes the Hebrew

Yes, you can pay with a kartis ashrai, but if you pay mezuman there's a small discount.

  • kartis ashrai כרטיס אשראי credit card
  • mezuman מזומן cash
Stock Parakeet guesses English

Pick up the forms for the Rishayoniski from Chana and ask her about the Vad and Hershikun while you're there.

Hebrish Jachnun v1.0 writes the Hebrew

Pick up the forms for the rishayon iski from Chana, and ask her about the vaad in her shikun while you're there.

  • rishayon iski רישיון עסקי business licence
  • vaad ועד residents' committee
  • shikun שיכון housing estate
Stock Parakeet guesses English

Hi Avi, I checked with the Sevet and the answer is yes. We can have the demo ready for the Reicheva client by Thursday.

Hebrish Jachnun v1.0 writes the Hebrew

Hi Avi, I checked with the tzevet and the answer is yes, we can have the demo ready for the Be'er Sheva client by Thursday.

  • tzevet צוות team
  • Be'er Sheva באר שבע the city
Stock Parakeet guesses English

S. D. Rabinowitz told me I still need to fill out a TOFS for the tax authority before the end of the month.

Hebrish Jachnun v1.0 writes the Hebrew

Esti Rabinowitz told me I still need to fill out a tofes for the tax authority before the end of the month.

  • tofes טופס form
Stock Parakeet guesses English

Did you see that the Mem Shalah just approved another round of funding for the cyber programme? Let's read the details tonight.

Hebrish Jachnun v1.0 writes the Hebrew

Did you see that the memshala just approved another round of funding for the cyber program? Let's read the details tonight.

  • memshala ממשלה government
Stock Parakeet guesses English

My Makshev died again this morning, so I'll be working for my phone until I get it to the shop.

Hebrish Jachnun v1.0 writes the Hebrew

My machshev died again this morning, so I'll be working from my phone until I get it to the shop.

  • machshev מחשב computer

Verbatim transcripts from the public benchmark, round of 2026-10-19. More on hebrish.app.

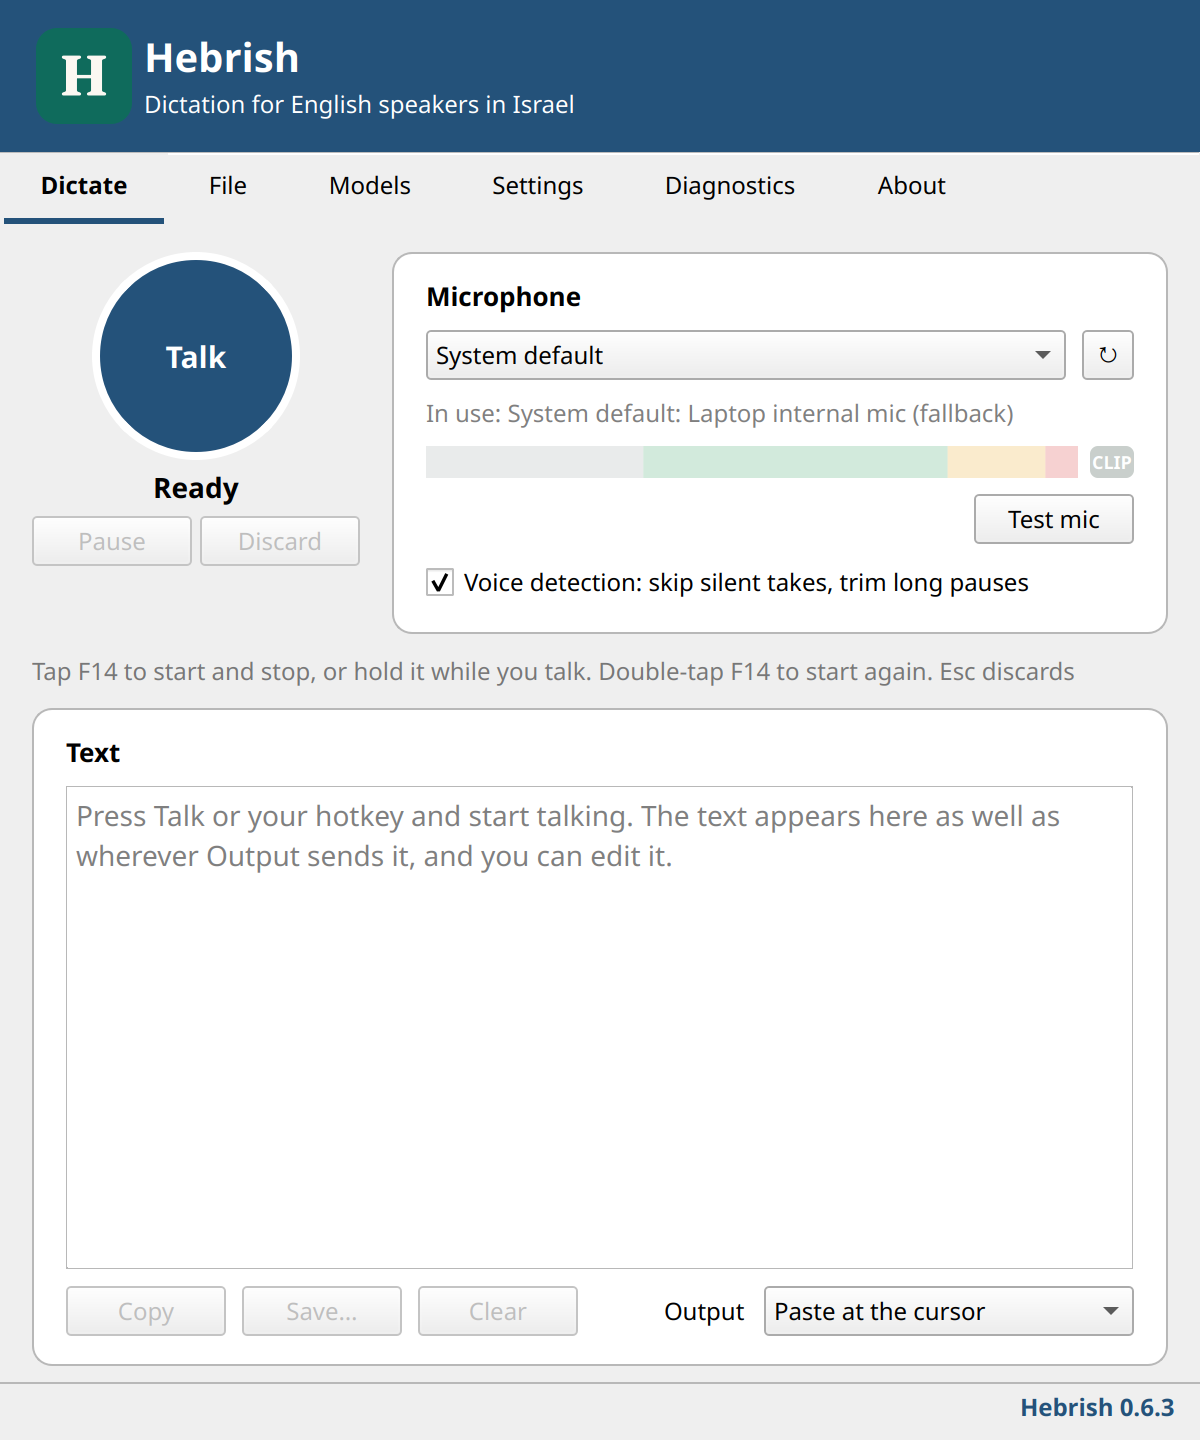
Hebrish 0.6.3 on Ubuntu, Dictate tab: a round Talk button, the microphone with its level meter, and the hint 'Tap F14 to start and stop'.
Dictate: press a hotkey anywhere, talk, and the text is pasted at the cursor.
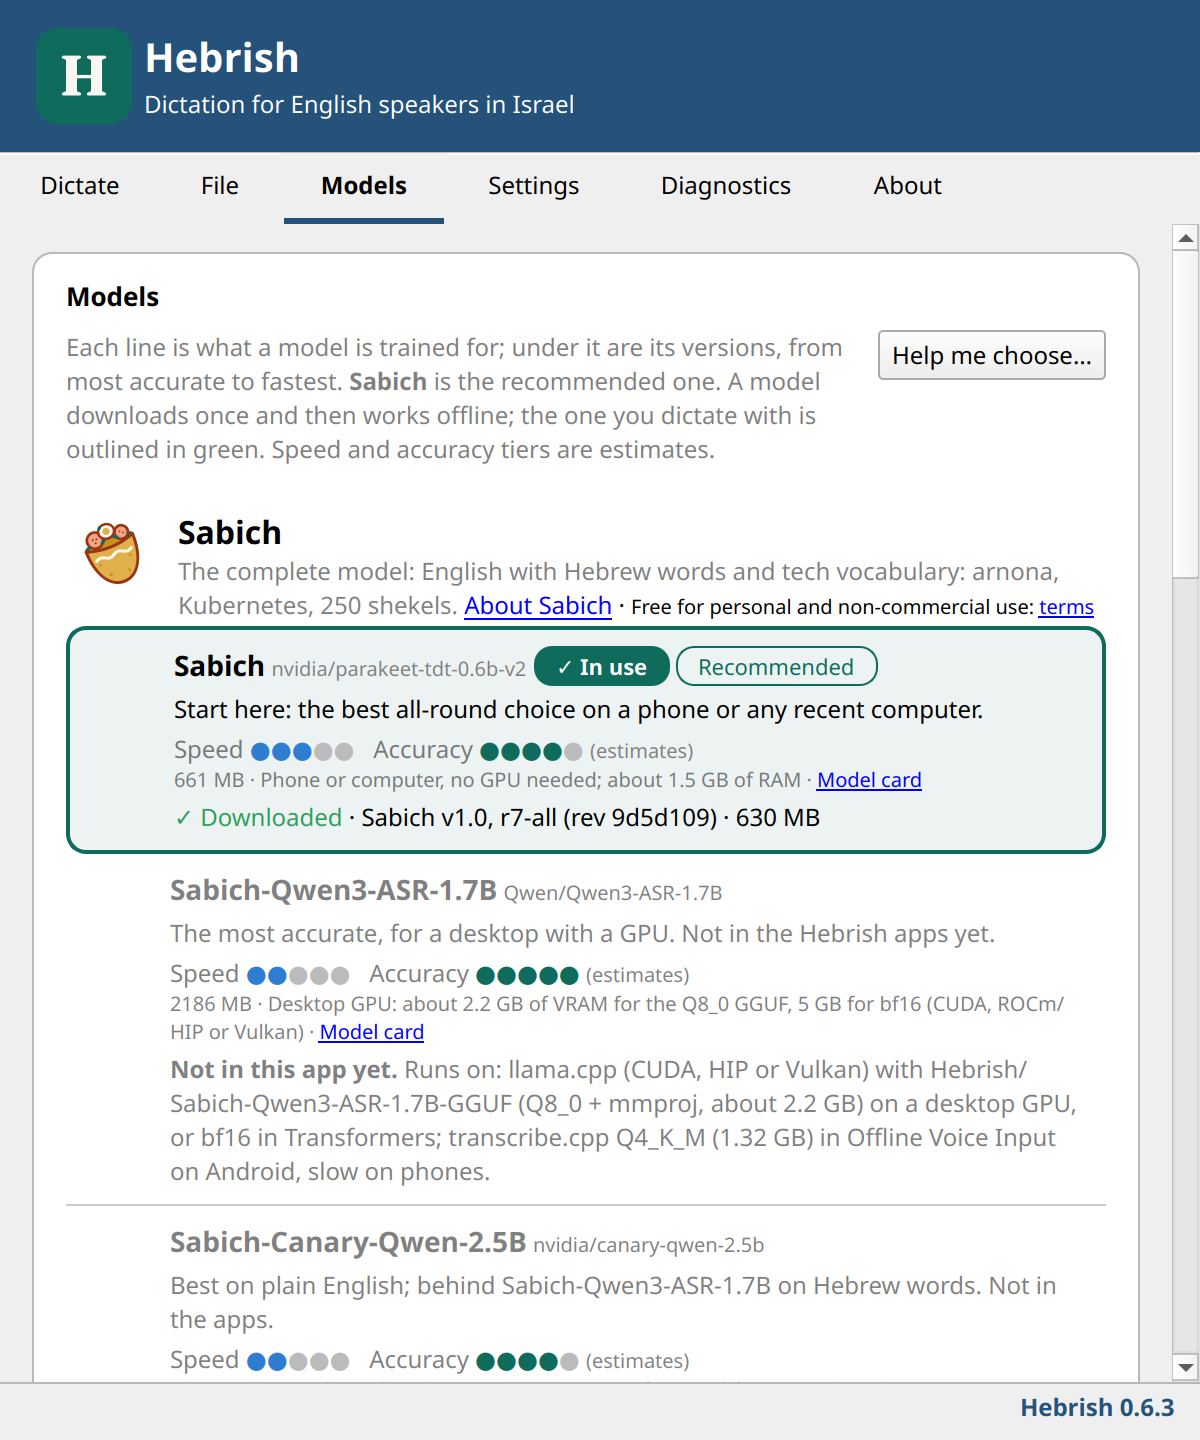
Hebrish 0.6.3 on Ubuntu, Models tab: Sabich in use and recommended, with speed and accuracy ratings for each model.
Models: Sabich is the recommended model; each download works offline.

Download the free apps ↗ for Android, Ubuntu and Windows. They run entirely offline.

Flagship models & datasets

The work I'd point you to first. Items with a card page open it; the rest go to Hugging Face or GitHub.

Hugging FaceModelHebrish (Sabich v1.0): Parakeet code-switching plus tech dictationHebrish/SabichThe recommended model in the Hebrish apps: Jachnun's code-switching data plus tech vocabulary, brands, numbers, Irish-English phrasing and my other task recordings, retrained from stock Parakeet v2. Level with Jachnun on code-switching (public benchmark term recall 73.8% against 73.3%), slightly better on tech (WER 1.54% against 1.74%). Also released on Qwen3-ASR 1.7B, Canary-Qwen 2.5B, Parakeet 110M and asr4all bases. Gated, access by request.Read the model cardHugging FaceModelHebrish (Jachnun v1.0): Parakeet English–Hebrew code-switchingHebrish/JachnunOn-device English dictation that writes Hebrew words correctly, in romanised Latin letters. Parakeet TDT 0.6B v2 fine-tuned on my own recordings, used through the Hebrish apps on Android, Ubuntu and Windows. Code-switched WER 11.8% to 5.4% (v1.0), plain English no worse. Use it if you mix Hebrew into English; for plain English, see Boxty. Site: hebrish.app.Read the model cardHugging FaceModelBoxty v1.0: Parakeet English and tech dictationHebrish/Parakeet-TDT-0.6B-v2-Tech-And-AccentThe sister model to Jachnun, for English dictation without Hebrew: tech vocabulary, brands, acronyms, numbers in digits and Irish-English phrasing, in my voice. Tech dictation WER 2.51% to 1.35%. It has none of the code-switching vocabulary, so use Jachnun if you mix Hebrew into English. Gated, access by request.Read the model cardHugging FaceSpaceEnglish–Hebrew code-switching ASR benchmarkdanielrosehill/English-Hebrew-Codeswitching-ASR-LeaderboardA replicable benchmark and leaderboard: stock and fine-tuned speech-to-text scored on how many Hebrew words in English speech they get right. Hebrish v1.0 (Jachnun): 73%; Whisper Large V3: 46%; stock Parakeet: 33%.Open the SpaceGitHubRepositoryHebrish KeyboardHebrish-ASR/Hebrish-KeyboardA full Android keyboard with Hebrish dictation on the mic key: a fork of HeliBoard, so there is no switching to a separate voice keyboard. GPL-3.0, arm64 only, early release. On the Hebrish F-Droid repository.View on GitHubHugging FaceSpaceASR Dataset Blenderdanielrosehill/ASR-Dataset-BlenderBuilds a training mix from Hugging Face speech datasets: filters, de-duplication, held-out sets that keep test terms out of training, and a share per source. Downloads NeMo manifests and a recipe pinned to each source's commit, so a blend can be rebuilt exactly. Source: github.com/Hebrish-ASR/ASR-Dataset-Blender.Open the SpaceGitHubRepositoryThe PC Benchdanielrosehill/The-PC-BenchDoes the model scold you? An eval for lecturing, moralising, terminology correction and unrequested disclaimers on legitimate requests, with mirrored Western-progressive and conservative triggers to measure selectivity. 54 open test prompts.View on GitHubGitHubRepositoryPropaganda Bait Evaldanielrosehill/Propaganda-Bait-EvalLoaded political premises across six series (CCP, MAGA, pro-Israel, pro-Palestine, Kremlin, US-progressive), scored on how readily a model repeats each framing.View on GitHubHugging FaceModelWhisper Hebrishdanielrosehill/Whisper-HebrishWhisper Large v3 Turbo fine-tuned for English speech with Hebrew words mixed in, the way English speakers in Israel talk.View model on Hugging FaceHugging FaceSpaceWhisper Hebrish demodanielrosehill/Whisper-HebrishTry the Hebrish model in the browser and compare it with stock Whisper.Open the SpaceHugging FaceModelHebrew-in-Latin token classifierHebrish/Hebrew-Latin-Token-ClassifierReleased: finds Hebrew words written in Latin letters inside English text ("the makolet"), so TTS can send them to a Hebrew voice. XLM-RoBERTa base, span F1 0.94 on a term-disjoint test set. No model for this existed before. Part of the Hebrish series since 2026-10-20. Demo Space and a Replicate API.Read the model cardHugging FaceModelGemma 3 270M ASR Paragraph Breaksdanielrosehill/Gemma-3-270M-ASR-Paragraph-BreaksNew (2026-10-20): adds paragraph breaks to flat speech-to-text output and changes nothing else, small enough to run on a phone after the ASR pass. Break F1 0.78 against 0.00 for the untrained model. ONNX export for ONNX Runtime.Read the model cardHugging FaceModelGemma 3 270M Email Key-Line Boldingdanielrosehill/Gemma-3-270M-Email-Key-Line-BoldingPreliminary (2026-10-21): puts the key parts of a dictated email (the requests, the purpose, the main points) in bold and changes nothing else. Runs after the paragraph-breaks model. Word F1 0.62 on 6 hand-annotated emails; the untrained model fell back on all of them. Demo Space.Read the model cardHugging FaceModelProximate Pseudonymizer 0.6Bdanielrosehill/Proximate-Pseudonymizer-0.6BProof of concept (2026-10-21): rewrites a text with identifying details swapped for close, plausible substitutes (Daniel to David, Jerusalem to Tel Aviv), used consistently. Not redaction. Qwen3-0.6B, Apache-2.0. It still leaves 9.3% of identifying details unchanged, so it is not safe to run unsupervised. Demo Space.Read the model cardHugging FaceSpaceLLM Spoken Steganographydanielrosehill/LLM-Spoken-SteganographyProof of concept: an LLM hides an encrypted message in the first letters of a mundane podcast script's sentences, which survive text-to-speech, playback through the air and speech-to-text. Grew out of My Weird Prompts #6141. Two-phone demo in the browser.Open the SpaceGitHubRepositoryPseudo-Personalised Spam Classifierdanielrosehill/Pseudo-Personalised-Spam-ClassifierPlanned: a small classifier that separates genuine email from strangers from mass outreach written to look personal, which gets past spam filters. Seed dataset of 18 pseudonymised emails on Hugging Face (2026-10-20); no model yet. The Pseudospam Filter plugin for Claude Code applies the same labelling standard today.View on GitHubHugging FaceDatasetHebrew-in-Latin code-switching corpusHebrish/hebrew-latin-code-switchingEnglish sentences with Hebrew words written in Latin letters, labelled at token level (BIO): the training set for the classifier above. No comparable corpus existed when it was built.View dataset on Hugging FaceHugging FaceDatasetEnglish–Hebrew Code-Switching Sentencesdanielrosehill/English-Hebrew-Codeswitching-SentencesSingle-speaker read-aloud audio of English sentences containing Hebrew words, for ASR fine-tuning.Read the dataset cardHugging FaceDatasetEnglish–Hebrew Mixed Sentencesdanielrosehill/English-Hebrew-Mixed-SentencesThe training set behind Whisper Hebrish: English sentences with everyday Hebrew vocabulary.View dataset on Hugging FaceHugging FaceDatasetRead-Aloud Voice Sentencesdanielrosehill/Read-Aloud-Voice-SentencesRead-aloud English and Hebrew sentences for fine-tuning Parakeet and other ASR models.View dataset on Hugging FaceHugging FaceDatasetTech Sentencesdanielrosehill/Tech-SentencesDeveloper and AI vocabulary read aloud, for ASR that has to get technical terms right.View dataset on Hugging FaceHugging FaceCollectionWhisper Hebrish (large-v3-turbo)danielrosehill/whisper-hebrish-691bc2624553319eb727c1dbWhere Hebrish started, in November 2025: a full fine-tune of Whisper large-v3-turbo for English with Hebrew words, with its demo Space and sentence data.View collection on Hugging FaceHugging FaceModelWhisper Hebrish Small ACFTHebrish/Whisper-Hebrish-Small-ACFTA phone-sized Whisper small.en fine-tune with FUTO's ACFT, for FUTO Keyboard and FUTO Voice Input on Android. 5.8% code-switching WER on its own test set.View model on Hugging FaceHugging FaceCollectionOn-device ASR on the OnePlus Nord 3danielrosehill/on-device-asr-one-plus-cph2493-nord-3ASR models I have tested running locally on an Android phone (OnePlus Nord 3, CPH2493).View collection on Hugging FaceGitHubRepositoryAndroid voice keyboard roundupdanielrosehill/Android-Voice-Keyboard-RoundupAn evaluation matrix of open-source Android voice keyboards and voice IMEs.View on GitHubHugging FaceDatasetNoisy Voice Notesdanielrosehill/Noisy-Voice-NotesReal voice notes recorded in rough conditions, for testing ASR beyond studio audio.View dataset on Hugging FaceHugging FaceDatasetASR WPM & background noise evaldanielrosehill/ASR-WPM-And-Background-Noise-EvalAnnotated recordings that measure how speaking rate and background noise affect ASR accuracy.View dataset on Hugging FaceHugging FaceDatasetTranscription Cleanup Trainerdanielrosehill/Transcription-Cleanup-TrainerPairs for fine-tuning a model to clean raw speech-to-text output into readable text.View dataset on Hugging FaceGitHubRepositoryCode Tutor Agentdanielrosehill/Code-Tutor-Agent-ModelAn agent configuration that guides a learner through a problem instead of doing it for them.View on GitHubGitHubRepositoryVibe Code And Learndanielrosehill/Vibe-Code-And-LearnA multi-agent code-generation setup with an educational loop built in.View on GitHub

What I focus on

English–Hebrew code-switching

Speech and text models that cope with "Hebrish" — the English-with-Hebrew-words that English speakers in Israel actually use. Off-the-shelf ASR mangles words like teudat zehut or mashkanta; I build the datasets and fine-tunes that fix that.

14 related projects ↑

Speech-to-text & on-device inference on Android

Whisper fine-tunes, ASR evaluations and small models that run locally on a phone. Most of my writing starts as voice, so I care about accuracy on real voice notes, background noise and fast on-device inference.

21 related projects ↑

Accessibility

Using AI to make technology easier to use: voice-first input instead of typing, TTS that pronounces Hebrew words correctly, and tools that reduce friction for people who work in more than one language.

11 related projects ↑

Benchmarks & AI safety

Evals for how models behave, not just how they score: does a model lecture the user, repeat propaganda when the premise is loaded, endorse conspiracy theories or assume everyone is American? Plus the speech benchmarks behind my ASR work. Open test prompts on Hugging Face.

3 related projects ↑

AI for education

AI that teaches rather than just does: tutor-style agents, learning loops for code generation, and My Weird Prompts, a podcast that explains a new topic every day.

2 related projects ↑

Websites

Hugging Face collections: Code Switching (English and Hebrew) · Hebrew ASR · Whisper Hebrish · Android STT favourites · Small ASR models · STT evaluations · STT cleanup (text post-processing) · My public audio datasets · Hebrew TTS · all collections →

Podcast

My Weird Prompts

A daily AI-generated podcast. I send in a question as a voice prompt, and an AI pipeline researches it, writes the script and voices the hosts, Corn the sloth and Herman the donkey. Topics run from AI and technology to geopolitics, health and history.

5,862 episodes published as of 14 October 2026, with new ones every day.

89,978all-time downloads
14,847downloads, last 30 days
2,274unique listeners, last 30 days
1,131of them in the US

Verified by Podtrac (IAB-certified) as of 13 October 2026. Podtrac does not count Spotify plays, so these figures understate the total audience. Show data portal
Work with me

Need speech AI, agent workflows or evals built for your team?

Everything on this site is open source and built in public. If you want the same kind of work done for your organisation, I take on consulting and build projects through DSR Holdings.